Kimi K3.1 Pro API price, bench, and when to use it
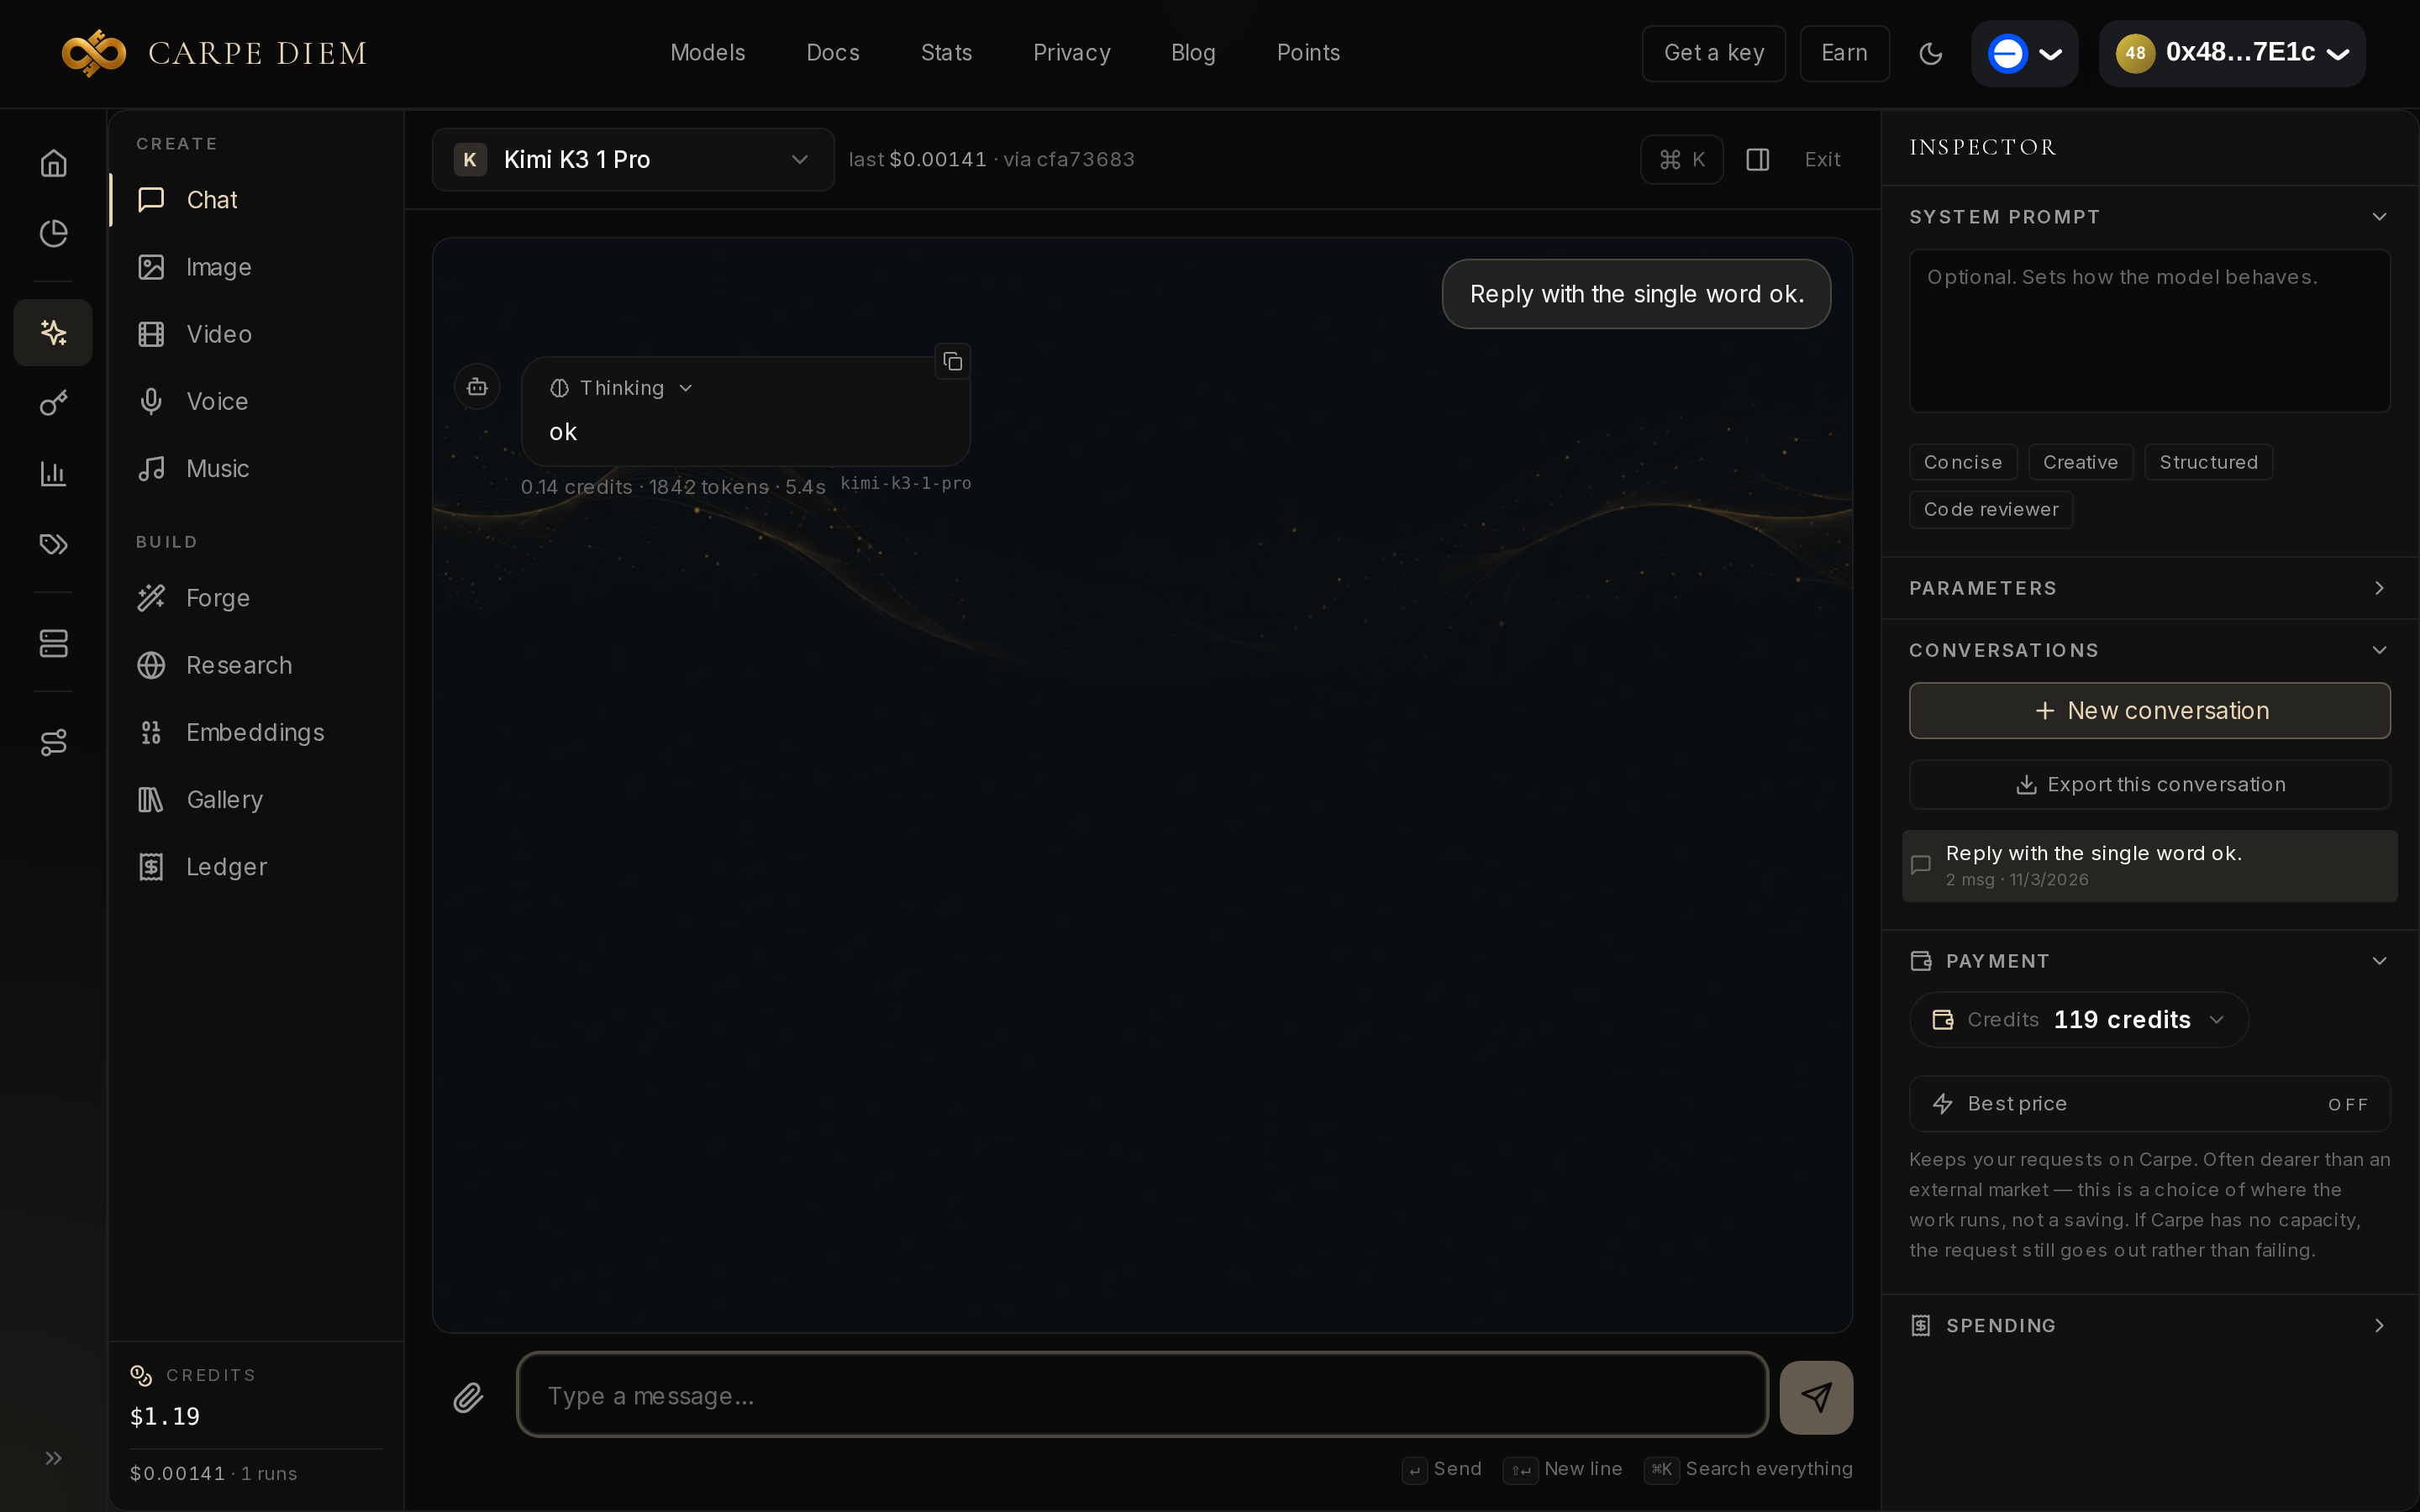
Kimi K3.1 Pro, the model Moonshot AI presented on 23 October, is available on Carpe Diem under the id kimi-k3-1-pro. At the time of our test, on 3 November, it cost $2.11 per million input tokens and $10.56 per million output tokens, versus $3.75 and $18.75 on Venice. It solved the arithmetic, the JSON, and the needle in a long text. It mainly makes sense if your stack is already built around Kimi.
Kimi K3.1 Pro in brief
Moonshot presents K3.1 Pro as the first model in its K3.1 series, a post-trained version of Kimi K3, multimodal, with a million-token context, aimed at long-horizon coding, 3D work, and financial research. The official announcement also promised full weights by 4 November; we have not checked whether they shipped.
The catalogue lists vision, reasoning, function calling, structured output, web search, and multiple images per request. It is classed anonymized: Venice forwards your requests to Moonshot, which sees the content but not the sender. If your prompts must stay on a private model, pick another one.
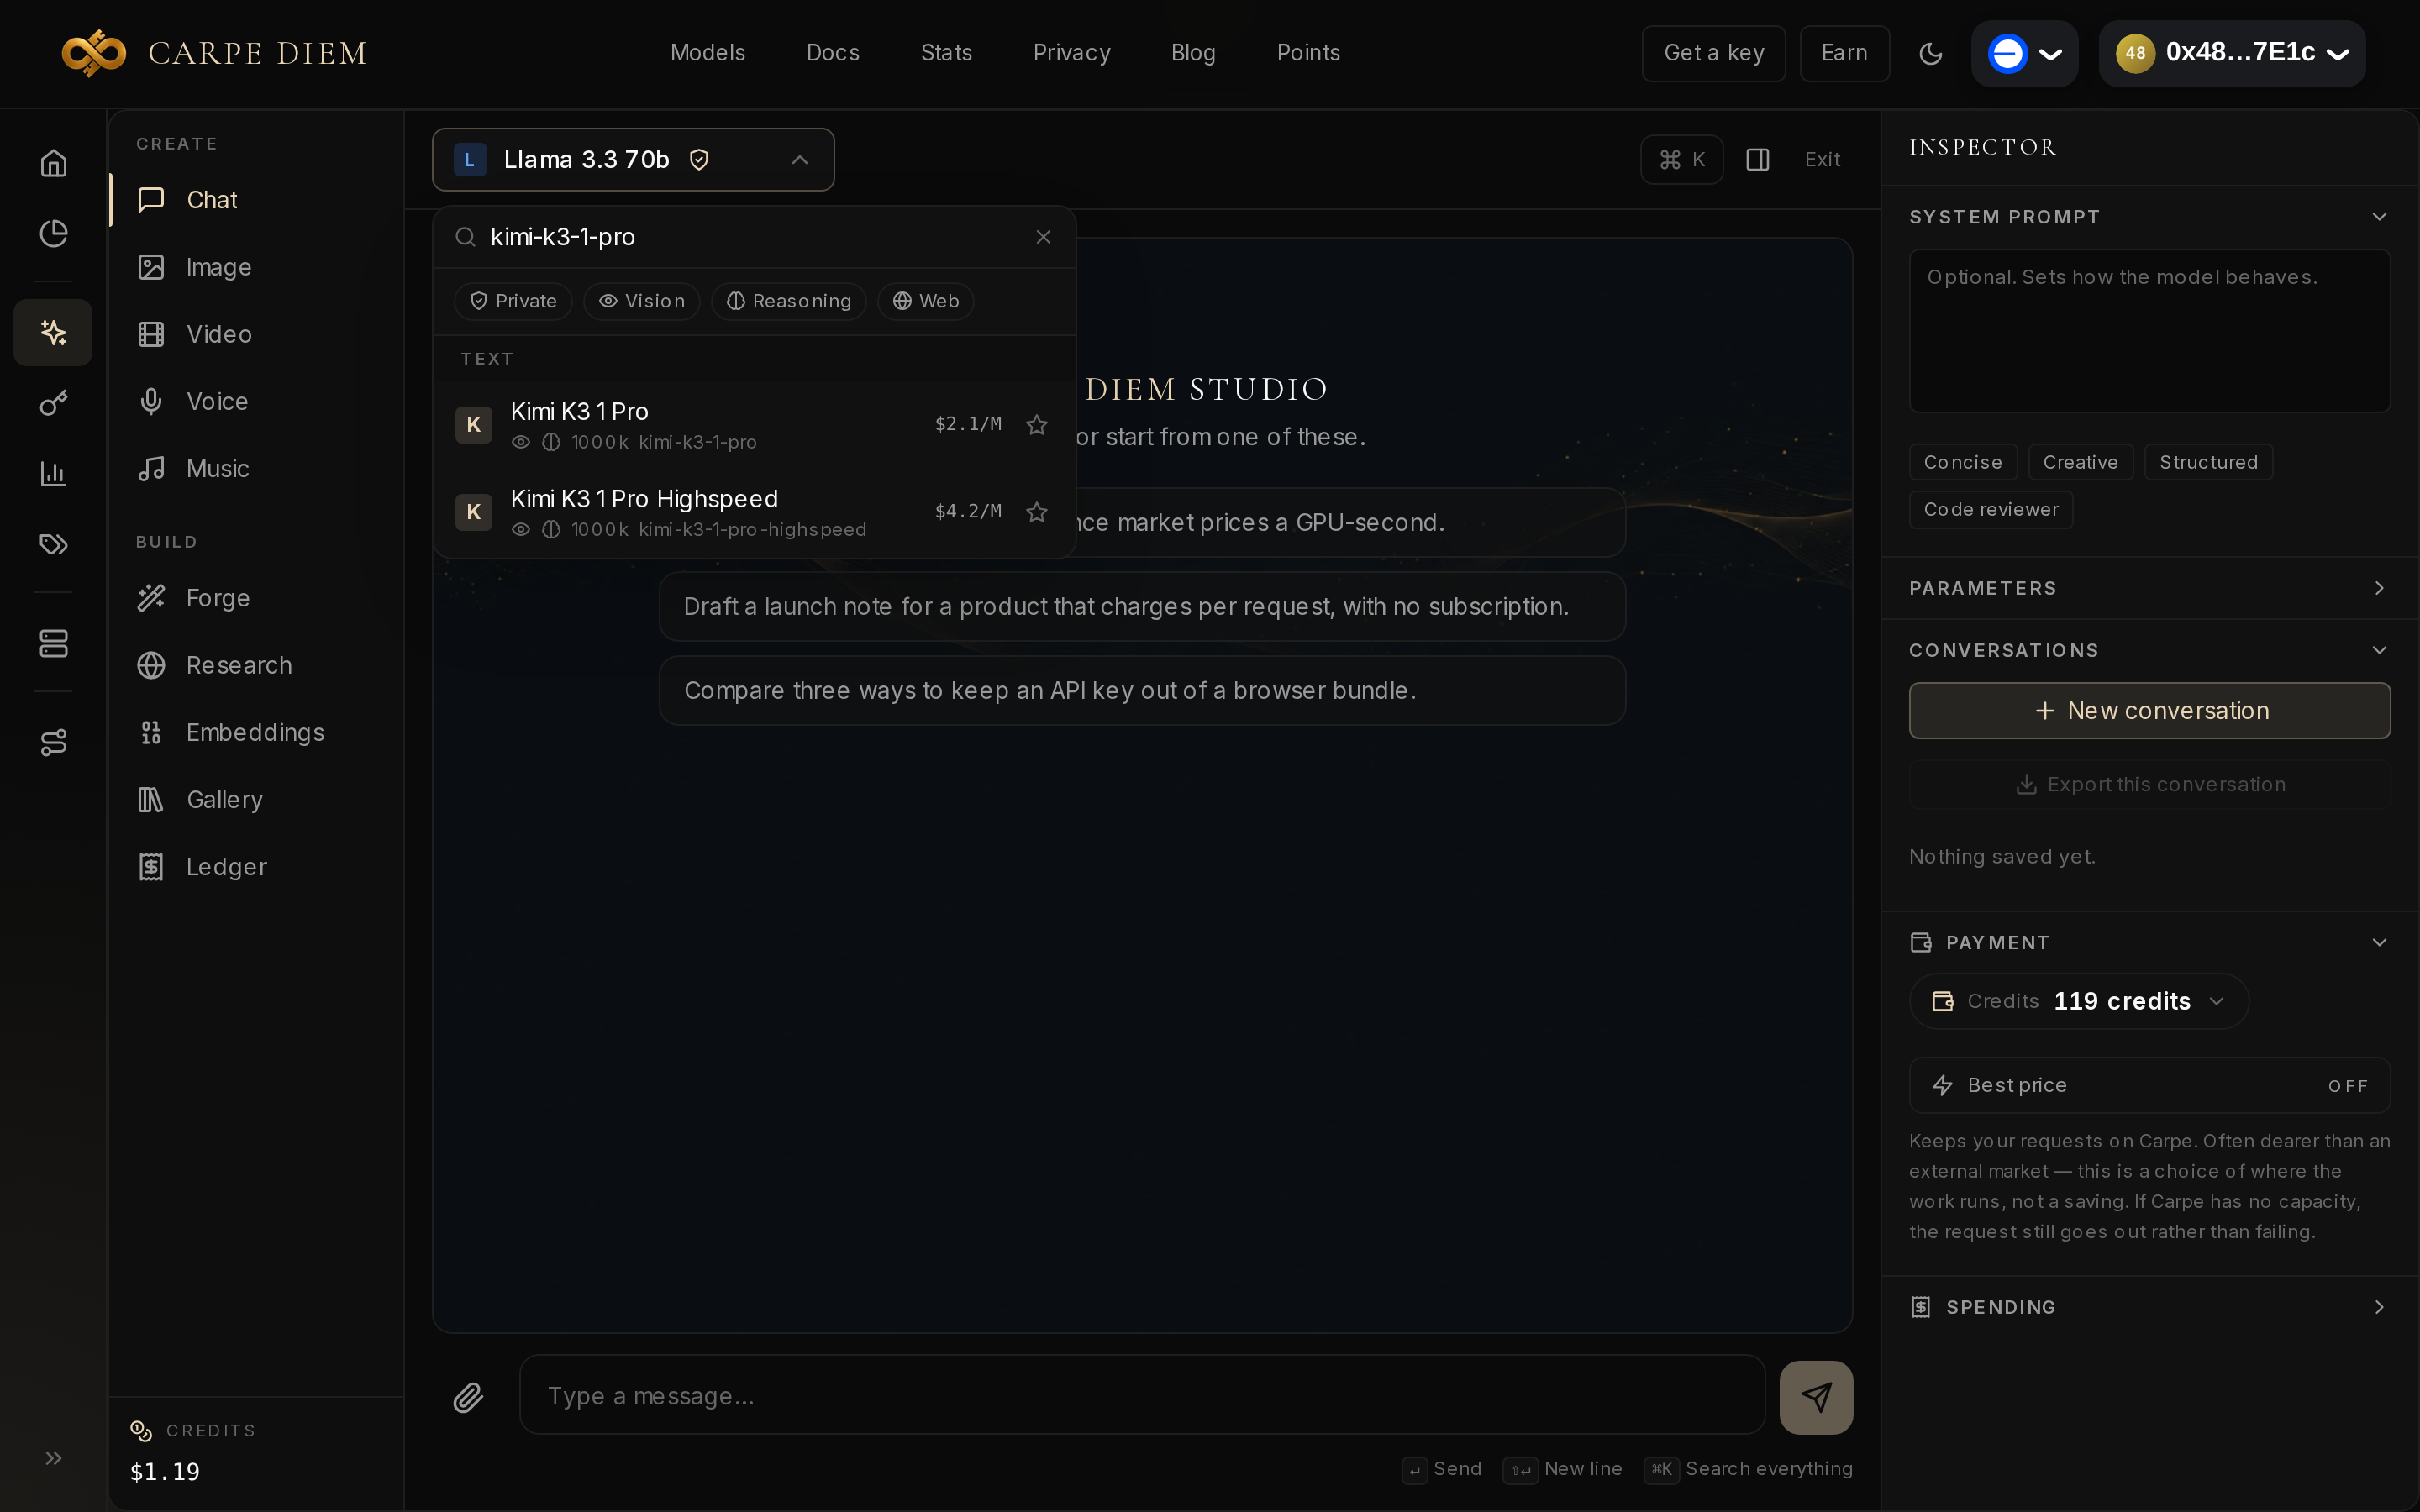
Price: $12.67 for a thousand average requests
A thousand requests of 1,000 input tokens and as many output tokens come to $12.67 on Carpe Diem, versus $22.50 direct on Venice. The price follows spare capacity during the day: check /models before you budget a large volume.
| Input / M | Output / M | 1,000 requests (1k / 1k) | Privacy | |
|---|---|---|---|---|
| Kimi K3.1 Pro (Carpe Diem) | $2.1114 | $10.5572 | $12.67 | anonymized |
| Kimi K3.1 Pro (Venice) | $3.7500 | $18.7500 | $22.50 | n/a |
| GPT-6.1 Terra | $0.5634 | $2.8172 | $3.38 | anonymized |
| Mercury 3 | $0.0563 | $0.1972 | $0.25 | anonymized |
Moonshot's rate card lists this model at $2 and $10 per million. The Highspeed variant, which we did not measure, showed at about twice that in the Hub picker.
For short, frequent calls, add venice_parameters.include_venice_system_prompt: false: without that field, Venice prepends its own system prompt, about 1,700 billed tokens on every call.
Bench: valid JSON in 4.8 s, arithmetic in 24.9 s
The full bench cost about $0.03. Kimi found the break-even threshold (40,000 requests) in 24.9 s, returned schema-valid JSON in 4.8 s, and retrieved the 7319-KESTREL marker hidden in a text of about 2,500 words. The French, 114 words on what a model router does, reads correctly. Moonshot says the model always reasons; we did not vary reasoning_effort.
| Test | Result | Duration |
|---|---|---|
| Reasoning (break-even) | correct, 40000 | 24.9 s |
| JSON extraction | valid | 4.8 s |
| Needle in ~2,500 words | found | 8.1 s |
| French writing | correct, no errors | 21.6 s |
JavaScript (compressRanges) |
6/6 outside the harness | 12.1 s |
The code-test harness did not find its test file and reported 0/6. The model had still returned a complete compressRanges function: extracted and run separately, it passes all 6 cases.
Kimi, GPT-6.1 Terra, or Mercury 3?
For JSON extraction or a short calculation, we would pick Mercury 3: it passes the same kind of tests for a fraction of the price, about forty times cheaper on input.
GPT-6.1 Terra is also cheaper than Kimi, with vision and the same anonymized status. Kimi makes sense in three cases: you specifically want the Moonshot model for agent coding, you need its million-token context, or your stack is already wired to Kimi.
First call with a Carpe Diem key
Create a cdm_ key in the dashboard, then export CARPE_API_KEY=cdm_your_key_here and OPENAI_BASE_URL=https://carpe-diem.xyz/api/operator/v1. The snippet installs nothing: urllib is enough.
import json
import os
import urllib.request

url = os.environ["OPENAI_BASE_URL"].rstrip("/") + "/chat/completions"
req = urllib.request.Request(
    url,
    data=json.dumps(
        {
            "model": "kimi-k3-1-pro",
            "messages": [{"role": "user", "content": "Reply with the single word ok."}],
            "venice_parameters": {"include_venice_system_prompt": False},
        }
    ).encode(),
    headers={
        "Authorization": "Bearer " + os.environ["CARPE_API_KEY"],
        "Content-Type": "application/json",
    },
    method="POST",
)
with urllib.request.urlopen(req, timeout=90) as resp:
    headers = dict(resp.headers)
    body = json.loads(resp.read().decode())

print(body["choices"][0]["message"]["content"])
usage = body.get("usage") or {}
print("prompt_tokens", usage.get("prompt_tokens"))
print("completion_tokens", usage.get("completion_tokens"))
print("x-carpe-cost-usdc-micro", headers.get("X-Carpe-Cost-Usdc-Micro") or headers.get("x-carpe-cost-usdc-micro"))
print("model", body.get("model"))
ok
prompt_tokens 92
completion_tokens 61
x-carpe-cost-usdc-micro 839
model kimi-k3-1-pro
Method: test on 3 November 2026, one run per task, short text only. Time to first token, vision, tools, reasoning_effort, the million-token window, and Highspeed were not tested.
The Hub is covered in the Create Hub article; the API, in the Python SDK. Create a key, run the snippet, or open kimi-k3-1-pro in the Create Hub.