Mercury 3 diffusion LLM: 54% below Venice on Carpe Diem
Inception released Mercury 3 on 19 October 2026. The next day, the id mercury-3 was already in the Carpe Diem catalogue. It is a diffusion LLM: tokens are refined in parallel, not one by one. Our bench confirmed reasoning, JSON extraction, and a needle in 2,500 words. On the scored trials we measured 78 to 387 tokens/s end to end, latency included in that figure. That end-to-end figure is not comparable to the 1,068 pure-decode tokens/s Inception quotes.
Illustration generated with seedream-v5-lite on Carpe Diem.
What Mercury 3 does, and what we tested
Mercury 3 is a text model from Inception Labs, with no image input and no audio input, and a 1,000,000-token context. The call is still a normal chat/completions request: parallel refinement happens on the server, not in the request body. The catalogue attributes reasoning, reasoning effort, function calling, response schema, and web search to it. We saw reasoning and valid JSON; we did not test function calling or web search.
Privacy is anonymized: Venice, the upstream inference provider, forwards the content to the maker without attaching your identity, unlike a private model such as Llama 3.3 70B. See the privacy page for the detail on that exact point.
$0.0464 / $0.1625 per million, 54% below Venice
Carpe Diem resells Mercury 3 inference through Venice, which is why we compare against Venice's public rate.
| Input / M tokens | Output / M tokens | |
|---|---|---|
| Carpe Diem | $0.0464 | $0.1625 |
| Venice | $0.1000 | $0.3500 |
Inception lists a price of $0.20 / $0.70 and, at launch, a price of $0.10 / $0.35 (50% off). Venice shows that launch rate. The Carpe Diem prices in the table are those of the bench of 20 October 2026; the catalogue can move. At the rate of that bench, 1,000 tokens of input and 1,000 tokens of output cost $0.00021; on Venice, $0.00045. A thousand requests of that shape cost $0.21 versus $0.45.
Llama 3.3 70B, proposed by default in Chat, is at $0.3032 / $1.2127 per million, for 128,000 tokens of context and private inference. MiniMax M3.1 Flash (minimax-m3-1-flash) is at $0.0812 / $0.3248 per million, with vision. We did not run it on the bench. Both remain more expensive on input and on output than Mercury 3.
Our measurements of 20 October 2026
The bench billed $0.00053 in total. Tokens/s in the table are output tokens divided by the full call duration, network latency included: on 83 output tokens, 78 tokens/s mostly means the call took 1.1 s, not that decoding is slow. We did not measure time to first token.
| Trial | Result | Duration | Tokens/s | Cost |
|---|---|---|---|---|
| Reasoning (single answer) | OK, 40000 | 2.4 s | 387 | $0.00018 |
| JSON extraction | valid | 1.1 s | 78 | $0.00004 |
| Needle (~2,500 words) | found | 1.5 s | 132 | $0.00008 |
| French writing | not scored (judged by reading) | 1.6 s | 228 | $0.00008 |
The reasoning item asked for the threshold where a plan at $12 plus $0.40 per thousand requests becomes strictly cheaper than $0.70 per thousand. With r in thousands of requests per month, the model wrote 12 + 0.40r < 0.70r, then r > 40, and answered 40000, which is the expected figure. That call billed 944 tokens of output for a few lines that were visible.
JSON output returned vendor, amount_usdc 42.50, date 2026-03-03 and the two line items, with no extra field at all.
The French text addresses the reader informally and stays generic. Code was not scored.
When Mercury 3 is worth it
We would pick it for cheap JSON extraction: a single trial was valid in 1.1 s, billed $0.00004. Validate on your own documents before going to volume. The short reasoning item on the price threshold landed on the right answer in 2.4 s.
Skip it if you need a private model or image input at all. Llama 3.3 70B remains the default option of the Chat studio, with a context of 128,000 tokens.
Try Mercury 3 in the Hub or via the API
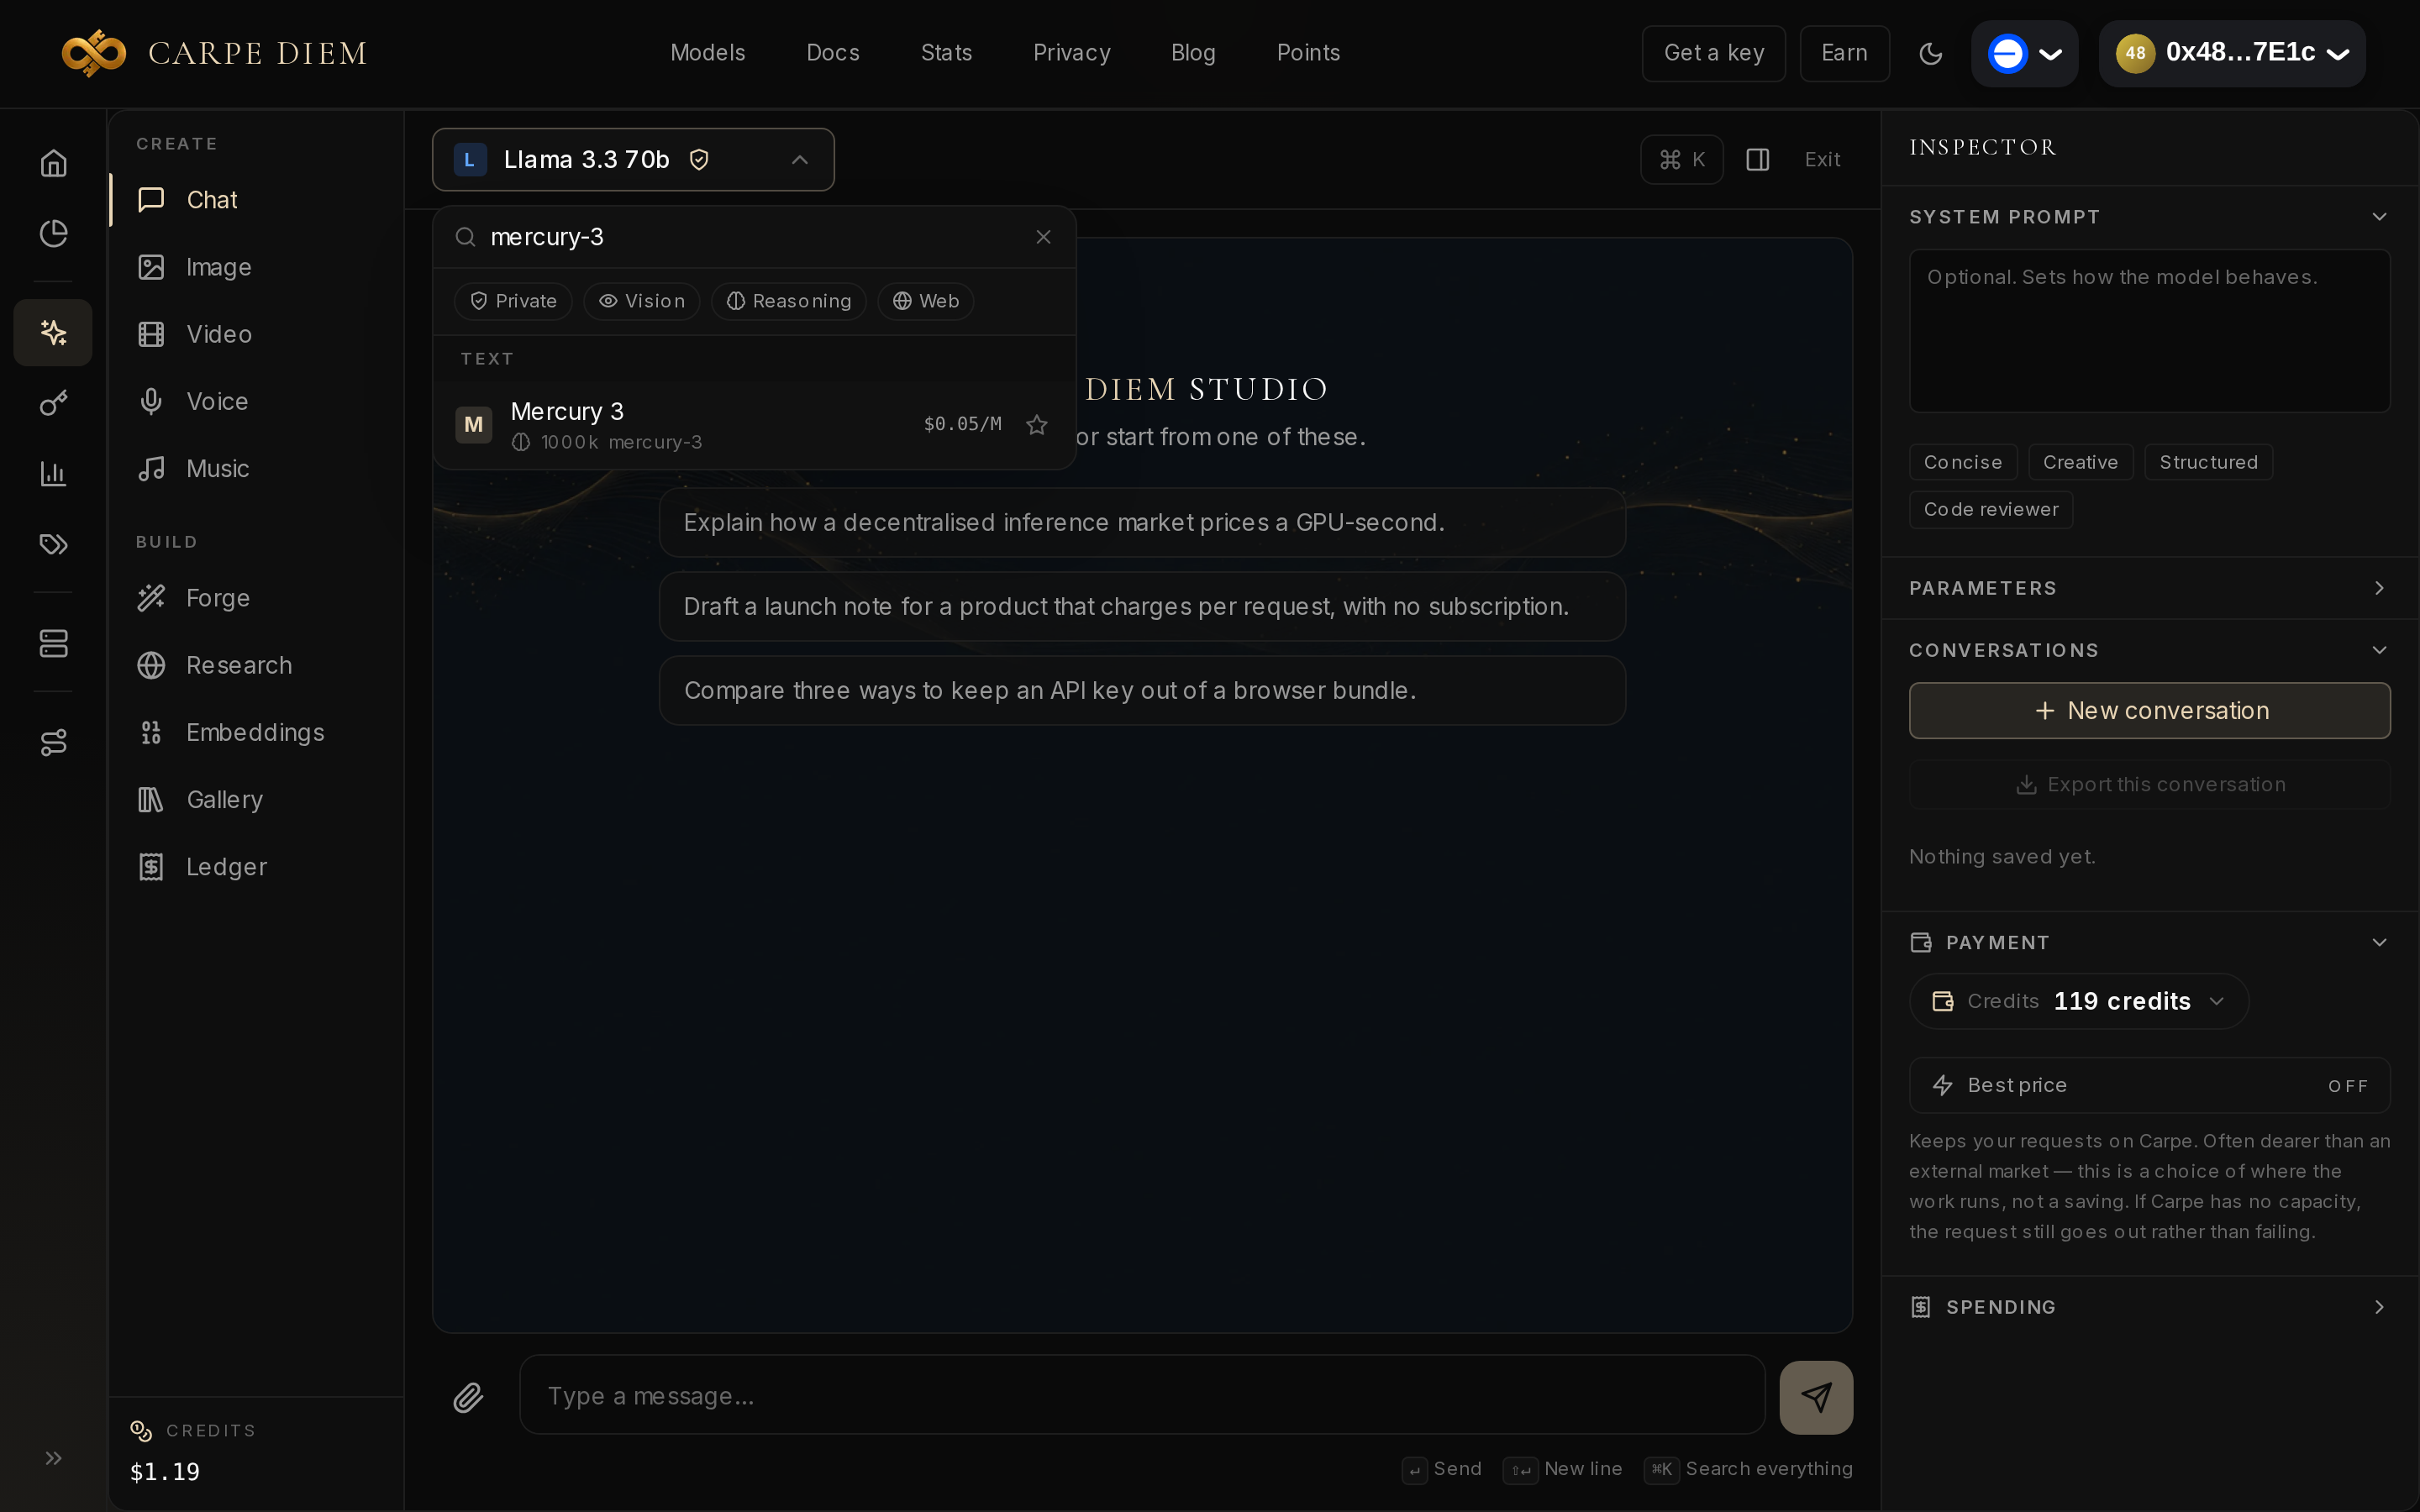
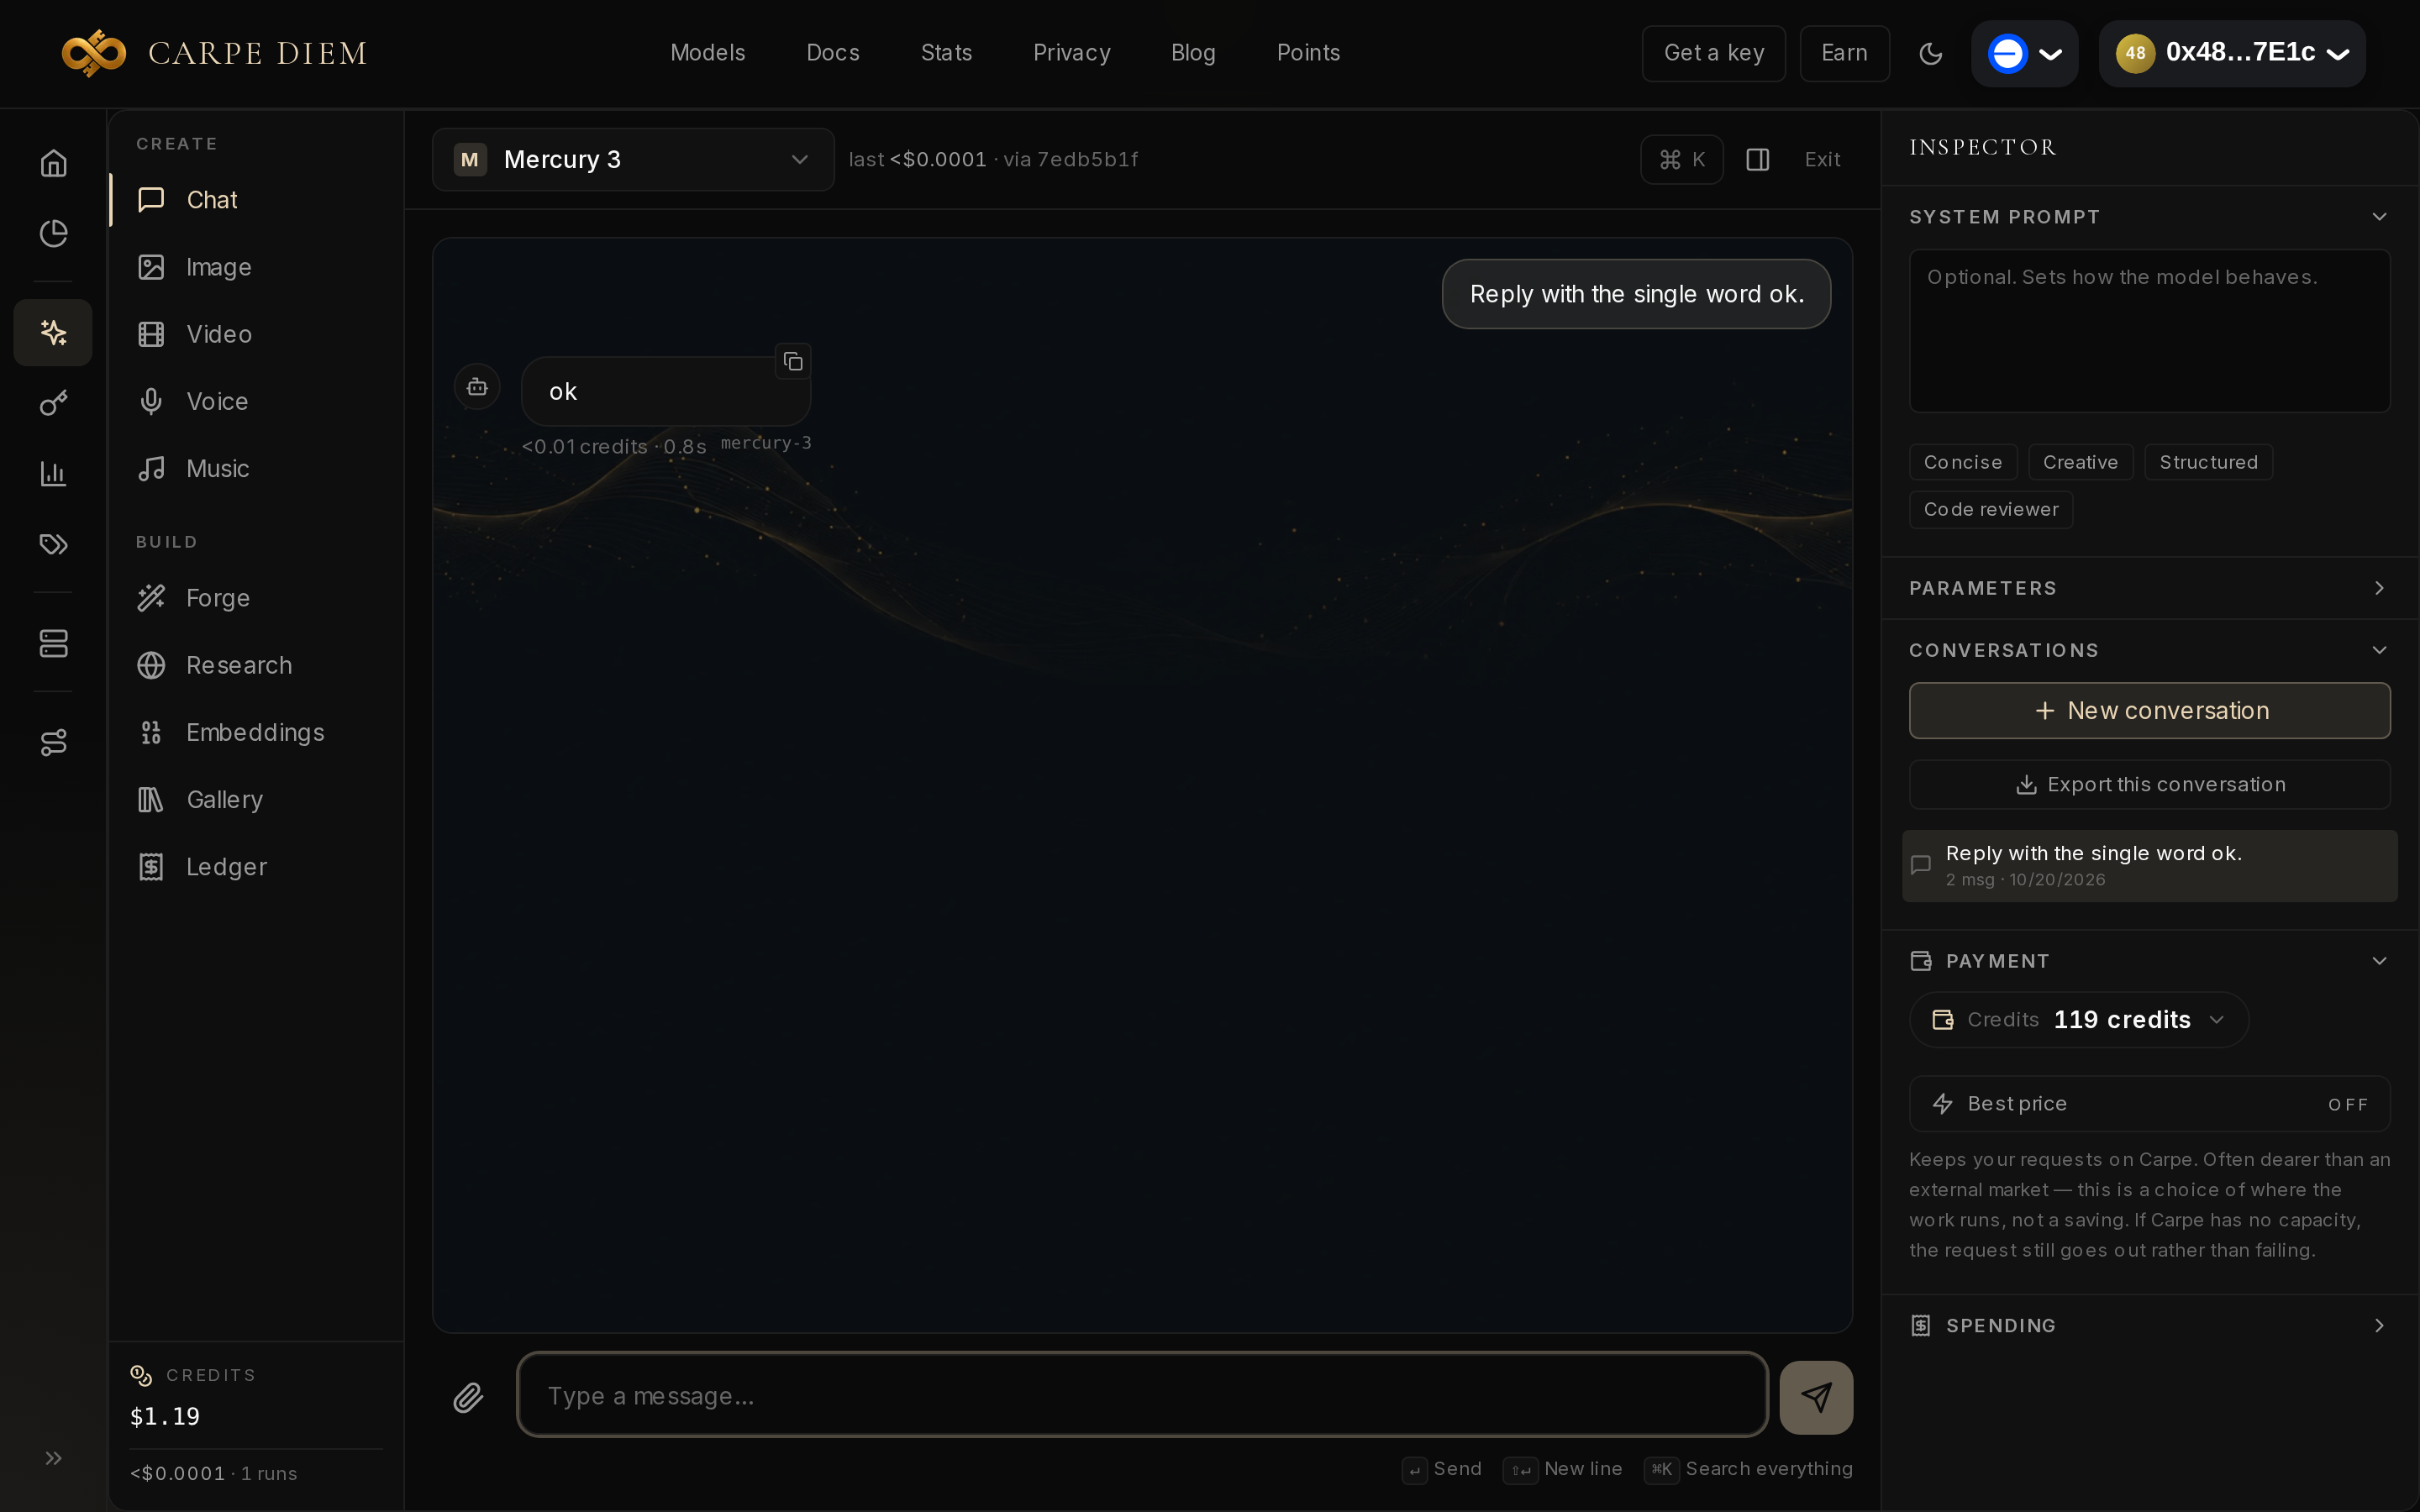
The Chat studio in Create Hub is enough on its own: open Chat, search mercury-3, then send a line. You do not need an API key; the session wallet pays in credits. A one-word prompt answered ok in 0.8 s, for under $0.0001. For the API, the following call ran (reply ok, 0.9 s):
curl https://carpe-diem.xyz/api/operator/v1/chat/completions \
  -H "Authorization: Bearer cdm_your_key_here" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "mercury-3",
    "messages": [{"role": "user", "content": "Reply with the single word ok."}]
  }'
Keys are created in the dashboard. The documented base URL for the API is https://carpe-diem.xyz/api/operator/v1 (docs, API reference). The playground is covered in the Create Hub article.